
When a user experience (UX) researcher says they’re swamped, believe it.
Because they do a lot of things: recruiting participants for research (usability tests, interviews, surveys, and whatnot), paying out incentives, synthesizing the research and sharing it with people that’ll make decisions based on it, and making sure the insights are stored somewhere safe so that they could be revisited six months down the line.
Thankfully, researchers don’t do all of this alone anymore (or at least, they shouldn’t have to). Back in 2018, a specialized practice emerged to handle the parts of the process that were masquerading as “research”. It started as a community founded by Kate Towsey, and has gotten more essential since: ResearchOps.
Cut to 2026, AI has redefined what ResearchOps actually covers. Two years ago, choosing a tool for research meant picking a transcription app. Today, it means deciding which aspects of your research process should be AI-first.
In this comprehensive guide, we cover the 6 core focus areas of ResearchOps, how AI has reshaped each one, and whether you actually need a dedicated ResearchOps hire or not. Bookmark this one, cause you’ll definitely want to return for a re-read 🔖
But first…
What Is ResearchOps?
Here’s how the ResearchOps Community defines it:
ResearchOps is the people, mechanisms, and strategies that set user research in motion. It provides the roles, tools and processes needed to support researchers in delivering and scaling the impact of the craft across an organization.
As a named discipline, ResearchOps is just a third-grader. It started when Kate Towsey, frustrated by how much of her job as a researcher had nothing to do with actual research, shared her woes to the world.
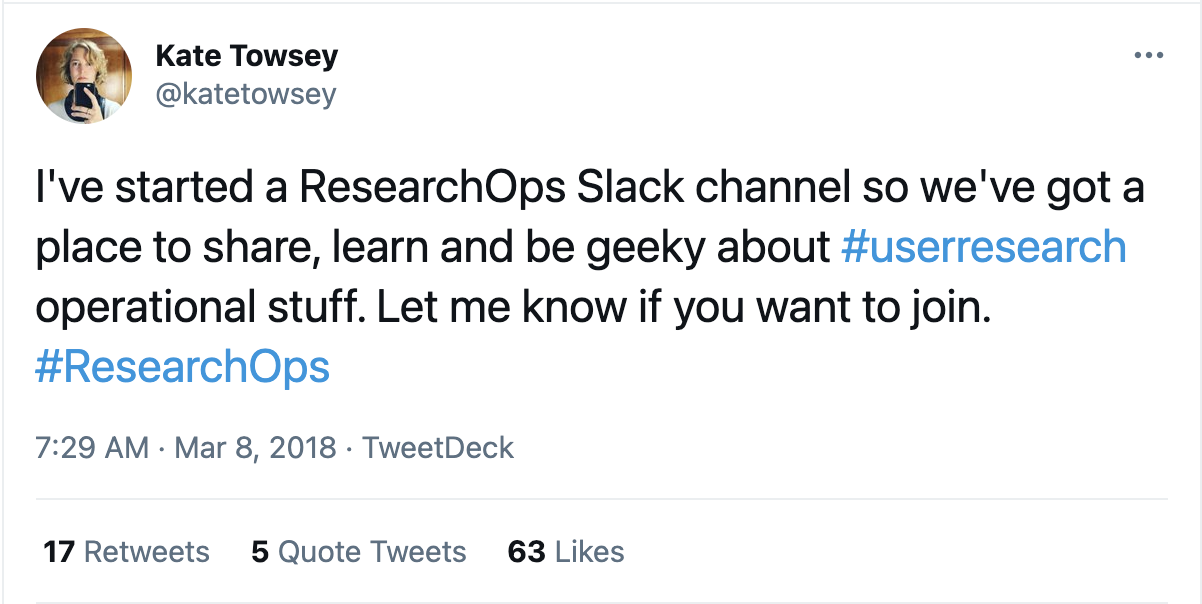
That tweet snowballed into what’s now a global community of research and ops practitioners across 100+ countries. And this isn’t a mature field with decades of best practices behind it. It’s young enough that a lot of organizations are still figuring out what “good” looks like (and that’s exactly where a guide like this helps💡)
Why should you invest in ResearchOps?
If you’ve scrolled (even absent-mindedly) till here, you’re probably wondering: does my organization actually need ResearchOps?
In 2026, more product managers and UX designers are running their own research studies (often with AI doing the heavy lifting) independently, making a stronger case for ResearchOps. If effective, here are three improvements you’ll observe:
Another lens to view ResearchOps through 🔎
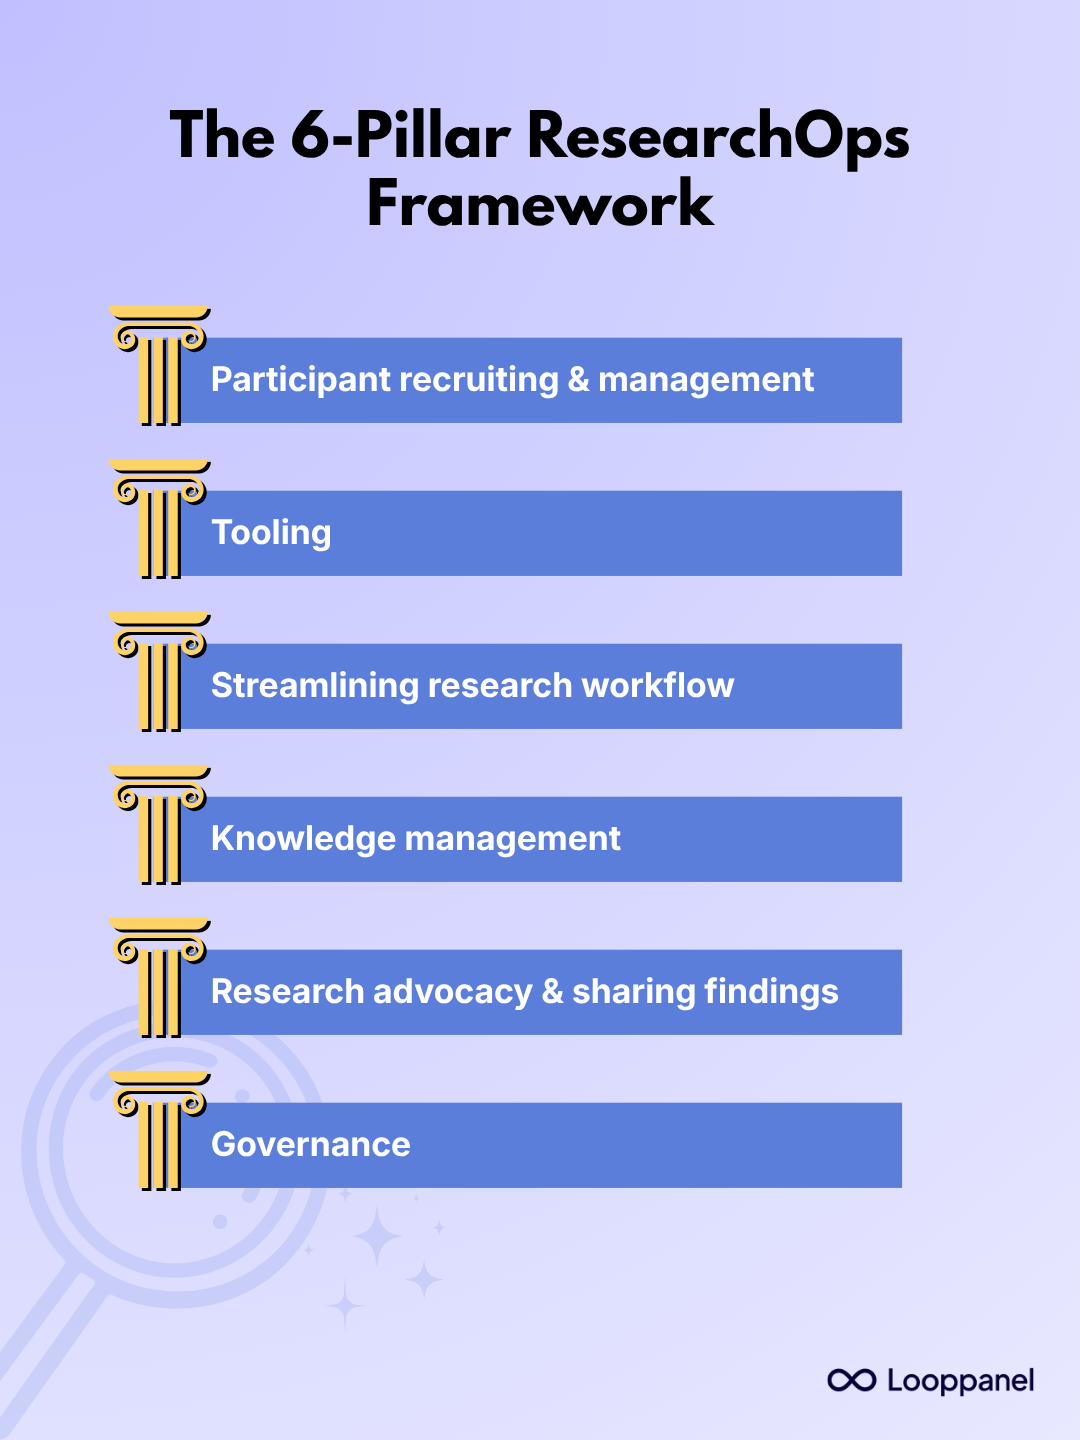
The spine of this guide is the classic 6-focus-area model (developed by Don Norman and Jakob Nielsen of NN/g), the most widely taught framework.
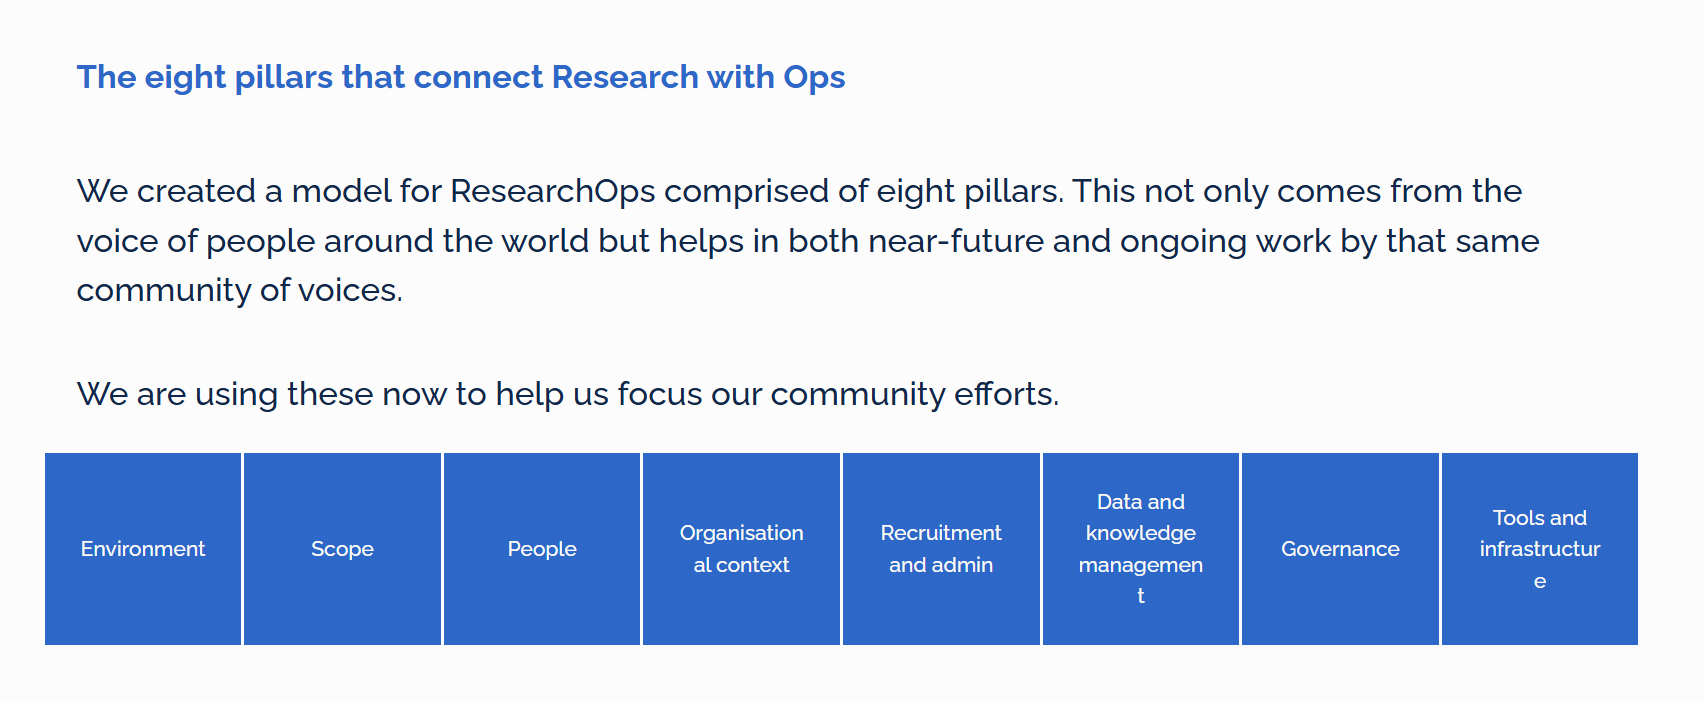
The ResearchOps Community itself developed an alternate 8 pillars framework: environment, scope, recruitment & admin, data & knowledge management, people, organizational context, governance, and tools & infrastructure. It’s not a competing philosophy because several of its pillars map directly onto the 6 areas you’ll read below.
The 6 focus areas of ResearchOps
ResearchOps is more than wrangling participants through screener surveys and emails. The actual scope can be mapped across 6 focus areas:
1. Participant Recruiting & Management
The first (and perhaps the most hated) aspect of research: coordinating a study with strangers who have no real incentive to show up (beyond a $40 gift card, that is), unpredictable schedules, and the eternal risk of your curated panel dissipating the night before your first session.
Under this pillar, ResearchOps covers:
- Building a database of potential participants (users or non-users)
- Shortlisting, screening, and finalizing the right people for a project
- Communicating, scheduling, and sending reminders
- Approving and distributing incentives fairly
But it all begins with one question: does this study need existing customers, or non-users?
Determine your target audience
Recruiting non-users
You can take one of these three routes:
- Recruiting platforms: Pre-screened pools, flexible scheduling, built-in incentive management (UserInterviews, Respondent.io, Askable, UserTesting.com)
- Recruitment agencies: Good for niche audiences, usually a few weeks of ramp-up time
- DIY recruiting: Cheapest, most labor-intensive (Online communities, social platforms, industry events, LinkedIn outreach)
You can check out our detailed guide on how to recruit non-users.
Recruiting existing users
Recruiting existing users can be a little more complicated (ironic, we know):
- Start by defining your segment. Are you looking for general users, or something specific (demographic, feedback-based, usage-based)?
- Build your outreach list. Check the right source: product analytics for general users, CRM for demographic segments, support/feedback tools for feedback-based segments.
- Pick your channel. If you have a large daily-active pool, go for in-product recruiting. If you are in the B2B space or have lower-engagement users, choose email outreach. You could also choose cold calling, but exercise caution: no one likes an unsolicited call about a usability study.
Here’s a guide on how to recruit existing users.
So, what does it cost?
According to the User Interviews’ Research Incentives Report, 74% of teams pay between $60–$100 per hour for moderated sessions, with $100 per hour being the single most common rate. For unmoderated studies, B2B typically ran $80–$100 per hour and B2C ran $50–$80 per hour.
Even a short session deserves a $20 minimum, or most participants won’t feel it was worth their time. And a compliance detail worth double-checking with your finance team: the general IRS threshold for reporting non-employee payments (1099-MISC/NEC) rose from $600 to $2,000/year starting in 2026, per the IRS. Whether research incentives specifically get reported this way can vary by how your organization classifies them.
2. Tooling
Good UX research takes time, effort, and as of 2026, some genuinely specialized AI tools. Here’s what ResearchOps manages on this front:
- Identifying what the team actually needs (note-taking, collaboration, analysis)
- Evaluating options against functionality, cost, and workflow fit
- Overseeing procurement and budgets
- Making sure everything meets compliance requirements
- Managing access, onboarding, and training
4 questions to ask before you evaluate a tool
Question 1: What’s the biggest pain point?
Talk to everyone doing research (researchers, PMs, designers, other stakeholders) to determine this. Skipping this step might be tempting, but it comes at a cost: 80% of research repositories fail because they’re brought on too early or with unrealistic experience.
Question 2: What’s the realistic budget?
Research tooling ranges from zero dollars (spreadsheets, Miro, existing email tools) to tens of thousands of dollars a year. Higher budgets help your organization unlock speed and fairness at scale.
Question 3: What’s the team’s natural workflow?
Do they have a notes-first approach? Transcript-first? Do they follow tagging or not? Whichever tool you choose needs to fit how your team already works, or it’s not going to get used.
Question 4: What are your future goals?
If you’re ramping up unmoderated testing or surveys next quarter, are you prepared to support that now?
Evaluation & purchase checklist
Check these eight things before you make a purchase: necessity, ease of use, features, integrations, collaboration, cost, privacy, and management.
The AI tool stack
Here’s how AI is showing up across your tool stack in 2026:
- Recruiting & participant management: Panels, screening, and scheduling are increasingly AI-assisted now, matching the right participant to the right study faster than manual screening ever could.
- Conducting research: AI-moderated interviews are a real, growing category now. But "real" doesn't mean "worth adopting by default." An AI moderator can run at a scale no human calendar allows, but it can't read a pause, chase an unplanned tangent, or adjust its tone for a participant who's clearly uncomfortable—and those are often exactly the moments that produce the insight a study was run for in the first place.
- Knowledge management: AI auto-tagging and theme clustering are now table stakes in a repository
- Governance: This is the fastest-growing piece of the list: who's allowed to touch AI-processed participant data, and what happens to it once they do. Every new AI capability (including MCP) comes with a set of questions that ResearchOps needs to answer: does this expose your research to AI tools beyond the one you intended? Could any of what it touches end up training a model it shouldn't? What access controls should exist before this gets switched on for the whole team?
A quick word on MCP
MCP (Model Context Protocol) is an open standard that lets AI assistants like Claude or ChatGPT pull answers directly from your actual research data instead of the open internet. You can avoid logging into three other separate tabs just to dig into your repository.
We recently shipped Looppanel MCP in beta, where you can connect your research workspace to your AI assistants and ask your queries in natural language to get answers grounded in real quotes and sessions.
3. Streamlining Research Workflow
This is where the ResearchOps team makes sure the actual day-to-day of research runs efficiently; and it’s crucial as teams scale.
Build a research playbook
A comprehensive playbook—methods, best practices, guidelines—is a lifesaver for onboarding, and encourages everyone to use the same templates instead of reinventing discussion guides every study. Keep it wherever your team already lives: Confluence, Notion, Google Drive, etc.
Build a repository
This is the fastest way to make research reusable (more in the Knowledge Management section below).
Train and empower researchers
Onboard new researchers, upskill the existing team, and train non-researchers too (if research is democratized at your organization) so they can run basic research responsibly when a researcher isn’t available.
Align cross-functional teams
Clear communication channels and regular check-ins keep research aligned with what the organization actually needs. Start with a monthly lunch-and-learn or a Slack channel for insight sharing between support and research, and then scale.
4. Knowledge management
This becomes the priority that ResearchOps just can’t ignore as research piles up.
When do you need a repository?
Here’s the sign to watch for: a PM asks, “What do we already know about how users feel about our integrations?”. And instead of a 10-second search, someone has to dig through a year’s worth of scattered Slack threads, old docs, and half-remembered reports. This means your research is piling up faster than it’s being organized.
Figure out your audience first: internal researchers struggling to find their own past work need a different solution than broader stakeholders wanting self-serve access. Also, centralizing your data doesn’t automatically make people search for it. Your repository won’t become self-serve on day one.
Common pitfalls
- Excessive manual tagging and taxonomy management (opt for tools that automate this)
- Building a repository without a real pain point or stakeholder buy-in
- Poor integration with existing workflows (Confluence, Jira, Notion)
- Forcing constant context-switching to analyze data outside the repository
How to know if your repository is actually working?
Check these three numbers quarterly:
A falling contribution rate usually points to a governance problem (no clear owner or process for getting studies into the repository), while a high time-to-first insight indicates a taxonomy problem (data is present, but not tagged or organized well enough), and a rising decay rate points to a maintenance problem (nobody's actually assigned to review, refresh, or archive old studies once they're in, so the repository fills up with outdated content).
5. Research advocacy & sharing findings with stakeholders
ResearchOps often plays intermediary between researchers and the rest of the organization, advocating for research’s value to the business.
What advocacy looks like
- Building case studies that tie research findings to real business metrics
- Regularly sharing insights: lunch-and-learns, newsletters, posters, etc.
How to share research insights effectively?
- Understand your audience. Different stakeholders have different priorities. Start with the people who influence UXR’s future in your organization.
- Choose the right channel. Formal decks for some, casual lunch-and-learns for others, and one-minute summaries for senior stakeholders.
- Highlight key insights
- Use storytelling. A well-woven narrative sticks better than a bullet list of findings.
- Encourage participation (Q&A, discussion, collaborative exercises)
- Solicit feedback and iterate. Ask if your communication is landing.
- Connect insights to business objectives. Offer concrete, actionable recommendations.
- Share success stories. These are proof that the research-driven approach actually worked.
TL;DR: If your study leads to a real outcome (a feature shipped or a costly redesign avoided), don’t stay quiet. Say it out loud in whichever channels people actually pay attention to: either a Slack channel or a monthly internal newsletter.
6. Governance
The final pillar, governance, ensures that research is conducted ethically and legally. This matters the most because you’re handling people’s personal information. ResearchOps plays a key role in:
- Staying compliant: ResearchOps stays up-to-date with data privacy laws (GDPR, CCPA, HIPAA, etc.) and ensures that your tools and processes adhere to these regulations, keeping your research practices always on the right side of the law.
- Establishing ethical processes: They help in creating processes and communication material that uphold ethical standards, like transparent consent forms, clear NDAs, etc.
- Managing participant data securely: They ensure that any personally identifiable information (PII) collected during research (names, birthdates, or email addresses) is properly stored, maintained, and disposed securely.
- Choosing secure platforms: They also prioritize secure tools for managing participant data like contact information, demographics, and consent forms.
An important side note
For any tool that uses AI, ensure that it doesn't train its base models on your data. This matters more than most governance checklists let on, and it's not just about your dedicated research tools. If anyone on your team is pasting interview transcripts into ChatGPT or Claude for a quick summary, that's the exact same exposure, just happening informally.
Alright, now that we’ve covered the 6 focus areas, time to answer another important question…
Do you ACTUALLY need a dedicated ResearchOps team?
With AI doing more of the legwork (MCP integrations pulling insights automatically, AI-moderated interviews running without a human scheduler, smarter panels matching participants on their own), it’s tempting to conclude that you can skip ResearchOps altogether.
In reality, while AI shrinks the headcount a ResearchOps function needs, it grows the complexity of what the smaller team is responsible for, especially:
- On the legal/compliance side: Who's allowed to touch AI-processed participant data? What is an AI moderator actually permitted to ask, and where do we draw the line? What happens to retention policy when an AI tool is the one doing your synthesis?
- On workflow judgment: Does an MCP-style integration genuinely fit how this team works, or does it just add another surface someone now has to govern? Not every AI capability is worth turning on just because it exists.
It’s time for you to invest in ResearchOps if you see these signs:
- Teams conducting studies on the same topics despite pre-existing research
- Insights get lost, past sessions are rusting in an old folder
- Recruiting is a constant fire that it blocks research from happening at all
- Nobody on the team can currently answer "where does our data actually go when an AI tool touches it"
If any of these sound familiar, you've got two real paths forward.
Option A: Hire dedicated ResearchOps
You need to hire someone who can evaluate whether a new AI capability actually fits your team’s workflow, and who owns the compliance risk if it doesn’t. This is a good fit if you can afford the extra headcount and you want your researchers focused on research, not managing tools and vendors.
Next, determine a salary budget, write a JD that reflects this evaluative, compliance-aware version of the role, and go hire your ResearchOps pro.
Option B: Distribute ResearchOps responsibilities across the team
This is a great fit if you’re early-stage, budget-constrained, or need a fast fix rather than a multi-month hire. You need to find your actual bottleneck, build templates to standardize the basics, and invest in the right tooling—before you invest in a dedicated ResearchOps person.
Phew! 😮💨 That was a lot to take in.
But now, you know the real scope of ResearchOps. Whether you’re building a dedicated ResearchOps function or IKEA-ing it across a small team, the six pillars haven’t changed. The only addition is AI fluency: knowing what MCP is, what an AI moderator can (and can’t) be trusted with, where your data actually goes, etc.
So configure your templates, build that repository, and maximize your spotlight by posting your wins 💪
P.S. When a shiny new AI feature asks for your research data, check where it goes before you turn it on.
Your peers also ask
What's the difference between a UX researcher and ResearchOps?
A UX researcher conducts studies and generates insights. ResearchOps builds and maintains the infrastructure—recruiting, tooling, governance, repository—that lets researchers do that work efficiently and at scale. Researchers ask the questions, and ResearchOps makes sure they can actually get answers without drowning in logistics.
Do small teams or startups need ResearchOps?
Not necessarily a dedicated hire, but the function is needed. Even a solo researcher benefits from lightweight templates, a basic repository, and clear recruiting processes.
How is AI changing ResearchOps in 2026?
Across all four practical jobs: faster recruiting via AI matching, AI-moderated interviews as a real research method, automatic tagging and theme clustering in repositories, and governance, since AI tools touching participant data raise new compliance questions that didn't exist two years ago.
What's the difference between a research repository and a knowledge base?
A research repository specifically centralizes raw research data, transcripts, recordings, and insights, usually tagged and searchable by study, participant, or theme. A knowledge base tends to be broader and more static with documentation, FAQs, process guides, etc. Some organizations merge them, but most keep them separate because people search for each one differently.
How much should I budget for research incentives?
Real data puts moderated interviews at $60–100/hour for most teams, with $100/hour the single most common rate. Unmoderated tests run lower: $50–80/hour for B2C, $80–100/hour for B2B. Keep a $20 minimum floor even for short sessions. One compliance detail worth confirming with finance rather than assuming: the general IRS threshold for reporting non-employee payments rose from $600 to $2,000/year starting in 2026, per the IRS — whether research incentives specifically fall under this can depend on how your org classifies them.
Is ResearchOps the same as DesignOps?
Related, not identical. DesignOps supports the design function broadly (tooling, process, critique structures); ResearchOps focuses specifically on the research function. Some organizations combine them under one ops umbrella, but the larger ones usually split them once research scales enough to need its own dedicated support.